NVIDIA Launches Open Nemotron 3.5 Super VL and Edge Bolt Models to Drive Enterprise Agentic AI Deployments

NVIDIA has announced the availability of Nemotron 3.5 Super VL, an open 120-billion-parameter multimodal model engineered for enterprise-grade autonomous agents, alongside new Nemotron 3.5 Bolt edge models designed to extend agentic AI capabilities across local enterprise workstations and branch infrastructure.
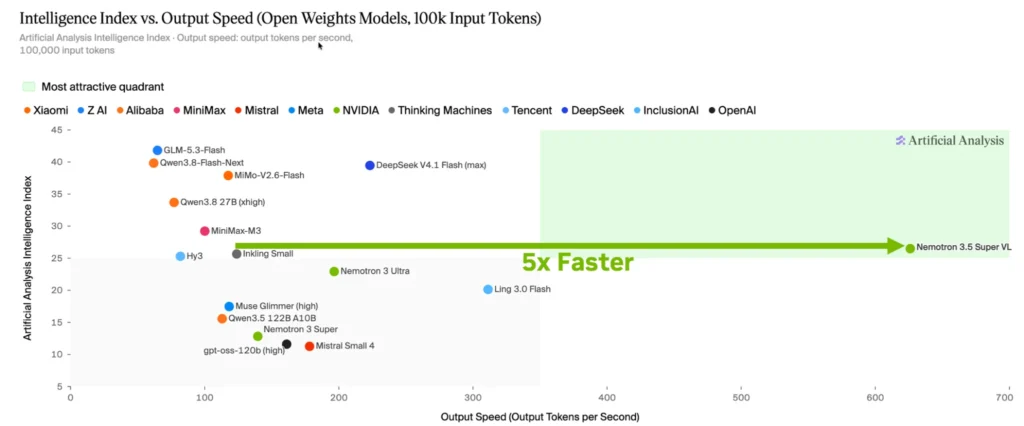
As enterprise IT leaders transition from passive generative assistants to multi-step, always-on autonomous agents, operational latency and compute costs remain major bottlenecks. Nemotron 3.5 Super VL addresses this via a Mixture-of-Experts (MoE) architecture that activates only 12B parameters per token. The architecture delivers frontier-grade accuracy across visual document intelligence, complex tool calling, and tabular reasoning at roughly one-fifth the parameter footprint of comparable flagship reasoning models, yielding up to 5x higher throughput on enterprise workflows.
Enterprise Data Sovereignty & Domain Customization
Unlike closed, proprietary cloud APIs, Nemotron 3.5 Super VL provides open weights, training recipes, and open datasets on Hugging Face. Enterprise IT teams and systems integrators can post-train and adapt the model using the NVIDIA NeMo platform on proprietary datasets, corporate policies, and internal APIs.
Early enterprise adopters report significant TCO and operational improvements:
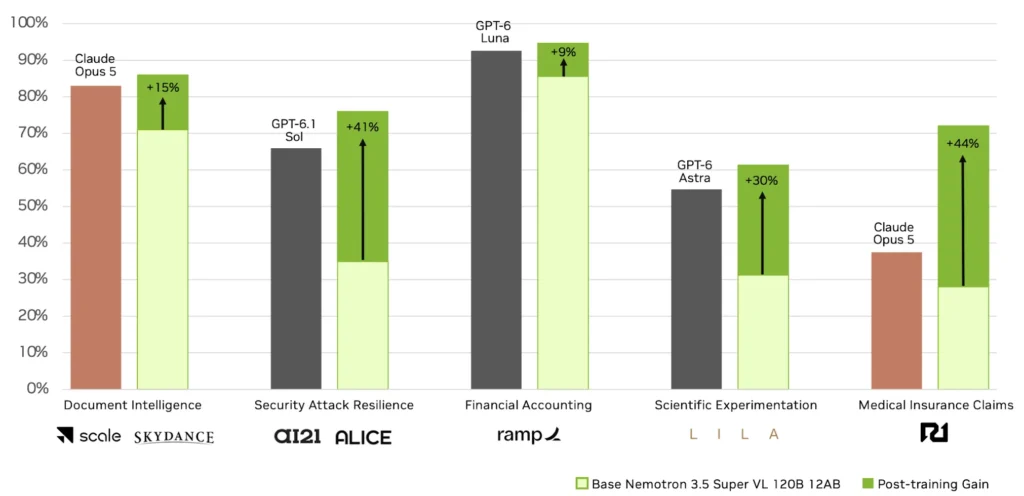
- Scale AI customized the model for automated financial vendor processing at Skydance, achieving a 40x reduction in inference cost and a 5x drop in latency.
- Ramp deployed the model for automated receipt and financial invoice parsing, unlocking up to 50% higher throughput with 10x lower latency.
- AI21 and cybersecurity teams post-trained the model for automated threat intelligence and vulnerability analysis, boosting triage accuracy by 41%.
Enterprise software leaders—including Atlassian, CrowdStrike, Salesforce, Perplexity, Dassault Systèmes, and Synopsys—are actively integrating the Nemotron 3.5 architecture into their platforms for Blue Team security operations, automated code verification, and ERP workflow execution.
Hybrid Deployment from Cloud to Edg
To meet strict regional data-residency mandates, organizations can deploy the model on-premises via NVIDIA NIM microservices—complete with bi-weekly enterprise security patching and performance enhancements—or execute local workflows via the new Nemotron 3.5 Bolt 74B-A9B on NVIDIA DGX Spark, DGX Station, and RTX PRO workstations within a 24GB memory footprint.
Nemotron 3.5 Super VL is accessible immediately through NVIDIA NIM, Hugging Face, and ModelScope.